

Technology that supports large-scale services
 |
Description
Book Introduction
This book is an introductory guide for engineers developing and operating large-scale services.
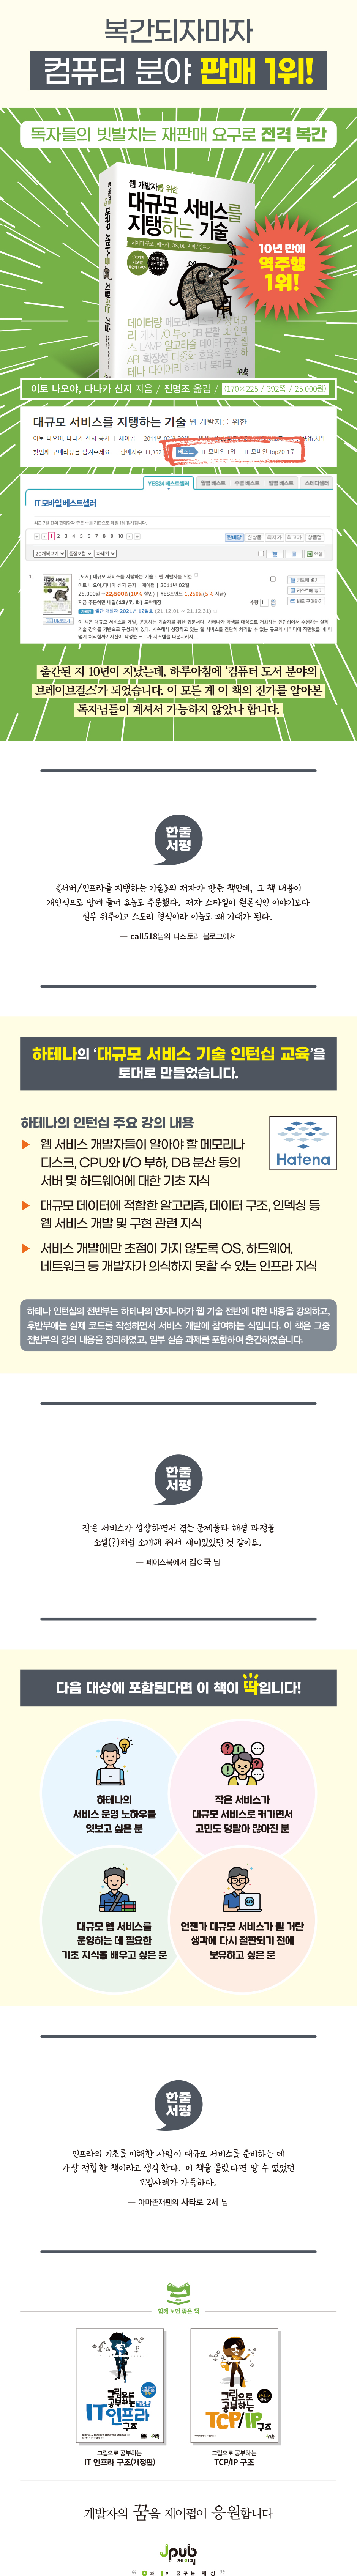
It is based on actual technical lectures conducted during internships held by Hatena for students.
How do you handle data that is growing beyond the capacity of a simple web service? What precautions should you take to ensure your code doesn't crash the system? What safeguards should you ensure when designing a system for scalability? This book covers a variety of practical techniques to address these issues.
The content includes a detailed introduction to the operating principles of OS and computers, DB distribution methods, how to apply practical algorithms to the system, the principles and structure of search engines that process large amounts of data, and infrastructure design knowledge for viewing the entire system, along with various sample codes.
In addition to this basic knowledge, it also introduces communication methods between engineers in Hatena's service development field, reasons for using tools, and goals, so it is full of information that will be helpful not only for development but also for team management.
Additionally, it will be helpful for those operating mid- to large-scale services to understand the potential issues that may arise when choosing whether to migrate all future services to the cloud, the considerations and prospects for using your own servers, and the barriers to globalization.
- You can preview some of the book's contents.
Preview
index
Chapter 1: Orientation to Large-Scale Web Service Development - Getting the Big Picture
Lecture 0 The Fundamentals of This Book - What It Explains and What It Doesn't Explain
Lecture 1 Large-scale and small-scale services
Lecture 2: The Wall of Continuously Growing Services and Scale
Lecture 3: Service Development in Action
Chapter 2: Introduction to Large-Scale Data Processing - Memory and Disk, Web Applications, and Load
Lecture 4: Data Size in Hatena Bookmarks - The more data you have, the longer it takes to process it.
Lecture 5: Challenges of Large-Scale Data Processing: Memory and Disk
Lecture 6: Elements of Scaling
Lecture 7: Fundamentals for Handling Large-Scale Data
Chapter 3 OS Cache and Distribution - Principles for Efficiently Processing Large-Scale Data
Lecture 8: Cache Structure of the OS
Lecture 9: How to Reduce I/O Load
Lecture 10: Dispersion that preserves locality
Chapter 4: DB Scale-Out Strategy - MySQL Operation with Distributed Deployment in Mind
Lecture 11: Properly Managing Indexes: The Basics of MySQL Operation Considering Distribution
Lecture 12: System Design Based on MySQL's Distributed and Scalable Architecture
Lecture 13: Scaling Out and Partitioning in MySQL
Chapter 5: Practical Introduction to Large-Scale Data Processing - The Keys to Application Development
Lecture 14: Purpose-Specific Indexing: Handling Large-Scale Data Proficiently
Lecture 15: The Battle Between Theory and Practice
Chapter 6 [Assignment] Compression Programming - Understanding the Relationship Between Data Size and I/O Speedup
Lecture 16 [Assignment] Compacting Integer Data
Lecture 17: VB Code and Speed
Detailed explanation and response examples for Lecture 18 Assignment
Chapter 7: Putting Algorithms into Practice - Putting Theory and Research into Practice with Close Examples
Lecture 19: Algorithms and Evaluation
Lecture 20: Keyword Links for Hatena Diary
Lecture 21: Categorizing Articles in Hatena Bookmarks
Chapter 8 [Assignment] Implementing Hatena Keyword Links - Understanding the Path to Application
Lecture 22 [Assignment] Creating a Hatena Keyword Link
Lecture 23: Response Cases and Thinking
Chapter 9: Challenges in Expert Search Technology - Know-How for Large-Scale Data Processing
Lecture 24: Applications of Professional Search Technology
Lecture 25: Architecture of Search Systems
Lecture 26: The Internal Structure of Search Engines
Chapter 10 [Assignment] Creating a Professional Search Engine - Basics, Detailed Writing, Pursuing Speed and Accuracy
Lecture 27 [Assignment] Creating a Hatena Bookmark Search
Lecture 28: Response Cases and Thinking
Chapter 11: Introduction to Servers/Infrastructure Supporting Large-Scale Data Processing - Web Service Backend
Lecture 29 Enterprise vs.
Web service
Lecture 30 Cloud vs.
Self-built infrastructure
Chapter 12: The Mindset Required for Scalability - Scaling and System Expansion
Lecture 31: Layers and Scalability
Lecture 32: Load Identification and Tuning
Chapter 13: Securing Redundancy and System Stability - Principles for Achieving Near-100% Uptime
Lecture 33: Ensuring Multiplicity
Lecture 34 System Stabilization
Lecture 35: System Stabilization Measures
Chapter 14: Efficiency Improvement Strategies - Increasing Hardware Resource Utilization
Lecture 36 Virtualization Technology
Lecture 37: Hardware and Efficiency Improvement: Elementary Technologies for Low Costs
Chapter 15 Web Services and Networks - The Growth of Services
Lecture 38 Network Junctions
Lecture 39 To a Higher Level
Special Edition: Practical Skills Required for Building Modern Web Services - To Respond to Large-Scale Services
Special Lecture 1: Job Queue System ㆍ TheSchwartz, Gearman
Special Lecture 2: Storage Selection: RDBMS and Key-Value Stores
Special Lecture 3: Cache Systems: Squid, Varnish
Special Lecture 4 Computational Clusters and Hadoop
Detailed image
Publisher's Review
The core authors of the best-selling book, "Technology that Supports Servers and Infrastructure (24/7/365)" have published another masterpiece.
This book generously shares the countless trials and errors, solutions, and core know-how in large-scale service development and operation that I acquired after a long and winding journey, starting with one server and operating 1,000 hosts.
Hatena, one of Japan's leading Internet companies that develops and operates services such as a 'knowledge community' human resource search service, a diary (blog) hosting service, and a social bookmarking service, will provide a good opportunity to examine Hatena's service operation know-how accumulated over the years and apply it to our reality.
This book is an introductory guide for engineers developing and operating large-scale services.
It is based on actual technical lectures conducted during internships held by Hatena for students.
How do you handle data that is growing beyond the capacity of a simple web service? What precautions should you take to ensure your code doesn't crash the system? What safeguards should you ensure when designing a system for scalability? This book covers a variety of practical techniques to address these issues.
The content includes a detailed introduction to the operating principles of OS and computers, DB distribution methods, how to apply practical algorithms to the system, the principles and structure of search engines that process large amounts of data, and infrastructure design knowledge for viewing the entire system, along with various sample codes.
In addition to this basic knowledge, it also introduces communication methods between engineers in Hatena's service development field, reasons for using tools, and goals, so it is full of information that will be helpful not only for development but also for team management.
Additionally, it will be helpful for those operating mid- to large-scale services to understand the potential issues that may arise when choosing whether to migrate all future services to the cloud, the considerations and prospects for using your own servers, and the barriers to globalization.
Because Hatena is actually used by 15 million users every day, it can deliver practical and vivid technology and a sense of presence.
Systematization of knowledge gained from the need to lead students participating in internships to the development field with only a few days of training.
By combining these, we have strived to create a book that is fun and readable, while also providing essential knowledge.
Book Support Webpage
Special Content (Japanese) http://gihyo.jp/magazine/wdpress/plus
Download sample code: http://gihyo.jp/book/2010/978-4-7741-4307-1/support
GOODS SPECIFICS
- Date of publication: February 28, 2011
- Page count, weight, size: 392 pages | 790g | 170*225*30mm
- ISBN13: 9788994506128
- ISBN10: 8994506128
You may also like
카테고리
korean


korean


